Using NORM
Using NORM to normalize your sociophonetic vowel data is relatively straightforward. In order to use NORM, you'll need to have your speakers' raw vowel data in a spreadsheet in the format described in the preparing your data section (below). You can also use our templates or view our sample files to help format your data. Once your vowel data are in the right format, you can simply to use the main NORM form to upload your files, select methods and options to normalize your vowel data and plot the results. You can use multiple methods to compare the results across methods or to the un-normalized values.
For information about how NORM works and for information about vowel normalization in general and the specifics of the various methods, see the About NORM page.
Note: NORM has changed as of version 1.0. The old templates are still available below. These still work, but note that the Context column is now optional.
Preparing Your Data
In order for NORM to process your data, they must be in tab-delimited text files with each speaker's vowel data in separate files. The files should start with one row that contains header information (e.g., "speaker","vowel", "F1", "F2", ...). The specific text of the header row is entirely up to you, provided that the columns are in the following order:
NORM version 1.0:
| Speaker Name | Vowel | F1 (onset or nucleus) | F2 (onset or nucleus) | F3 (onset or nucleus) | F1 (glide, if any) | F2 (glide, if any) | F3 (glide, if any) |
NORM pre-version 1.0:
| Speaker Name | Vowel | Context | F1 (onset or nucleus) | F2 (onset or nucleus) | F3 (onset or nucleus) | F1 (glide, if any) | F2 (glide, if any) | F3 (glide, if any) |
Each row in your file should contain the data for one vowel instance. Your spreadsheet should contain measurements for individual vowel tokens, not mean values.
The three glide columns on the right (and the context column) can be left blank, but you must enter values for the speaker, vowel, and the first set of formant values for each vowel. As of NORM version 1.0 you can include any number of additional columns in the table to the right of the F3 (glide, if any) column. While you can name each speaker and vowel type anything you want, you must use the exact same text for each row belonging to that speaker. Similarly, vowel measurements are grouped together according to what you name the vowel, so ensure that you give each token of the same vowel the exact same identifier. Also note that whatever you enter in the vowel column will be printed on your plots.
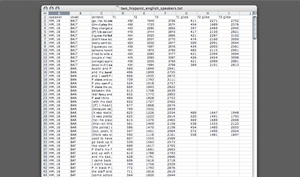
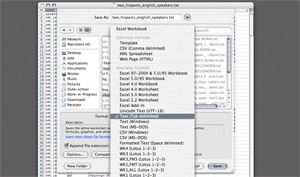
The easiest way to make a tab-delimited text file is to build the file as a spreadsheet in MSExcel or OpenOffice.org. When you've entered (or copy/pasted) all of your data into the file you can simply save the document as a Text (Tab delimited) file. A sample file (pre-version 1.0) is illustrated by the screenshot in Figure 1 and available for download (below); Figure 2 shows the "Save As..." window in MS Excel (on a Macintosh). We recommend you download one of our templates to use. You're also welcome to download a sample file, which you may find illustrative to look at or to test NORM with.
Download: (you may need to right-click and select "Save File As...")
- Templates:
- NORM Version 1.0 Sample Files:
 NORM-10_CentralOhioSpeakers.txt
 [ Central Ohio, White Male, born 1983, & White Female, born 1981; 32 kb ]
- Sample Files from NWAV 36 Workshop (Pre-version 1.0):
Speaker Pairs:
- CentralOhioNORM.txt
[ Central Ohio, White Male, born 1983, & White Female, born 1981; 32 kb ]
- EarlyNCS_NORM.txt
[ Northern Cities Shift (Early-Stage) English Speakers, Urban White Male, born 1946, & Rural White Female, born 1987; 28 kb ]
- HispanicEnglishNORM.txt
[ South Texas, Hispanic English Speaking Male, born 1987, & Female, born 1993, from Pearsall, TX; 32 kb ]
- NWAV_StMartinLA_NORM.txt
[ Southern Louisiana, Two African American Males, born 1918 & 1947 (No F3 values, don't use for Bark method); 24 kb * Thanks to Sylvie Dubois and Malcah Yaeger-Dror for sharing the data ]
- NWAV_TwoNYC_Speakers.txt
[ African American Female, born 1977, from Bronx, & White Female, born 1980, from Brooklyn; 24 kb * Thanks to Gregory Guy, Kara Becker, Libby Coggshall, and Cara Shousterman for sharing the data ]
- SpanishSpeakersNORM.txt
[ South Texas, Spanish Speaking Male, born 1938, & Female, born 1926; 8 kb ]
- TurkishSpeakersNORM.txt
[ Turkish Speaking Male, born ca. 1970, & Female, born 1980; 4 kb ]
- Tyrone_NORM.txt
[ Rural Northern Ireland, English Speaking Male, born 1943, & Female, born 1919; 32 kb ]
Groups of the above speakers:
- EightSampleSpeakers.txt
[ Central Ohioan English, Hispanic English, Spanish, and Turkish Speakers Combined; 72 kb ]
- EarlyNCS_And_MexAm.txt
[ Early NCS and Hispanic English Speakers Combined; 60 kb ]
- CentralOhioAndMexicanAm.txt
[ Central Ohioan and Hispanic English Speakers Combined; 64 kb ]
- CentralOhioAndTyrone.txt
[ Central Ohioan and Northern Irish English Speakers Combined; 64 kb ]
|